MergeTree Sort Key Design for Pre-Flattened Wide Tables
How to order columns in a MergeTree table to balance pruning and compression.
Designing a MergeTree sort key for a pre-flattened wide table means balancing query pruning, compression, and the cost of rewriting data. The best design follows access patterns that have been measured. That requires understanding what the sparse index can skip, what physical ordering can compress, and how both choices play out across dozens or hundreds of columns.
What pre-flattening does to the sort key problem
Pre-flattening collapses joins into a single table, but it also concentrates decisions that were once spread across smaller tables. Dozens or hundreds of promoted columns now compete for positions in one ORDER BY. They cannot all lead it. A column that is useful for one query may be a poor starting point for another, while columns rarely used in filters may still offer useful compression when grouped together.
That competition is unusually consequential because ORDER BY serves two roles. It defines the physical row order within each part and, unless a separate PRIMARY KEY is specified, defines the sparse primary index. Wide-part format gives each column its own file, so background merges rewrite many files, while weak pruning wastes reads across the columns a query needs.
The native JSON type, with max_dynamic_paths, reopens the earlier question of whether every useful field needs to become a physical column. But that is a different design decision. For teams already operating wide pre-flattened tables, the immediate problem is how to order the schema they have, without treating every promoted field as an equally strong index candidate.
How the sparse primary index actually prunes granules
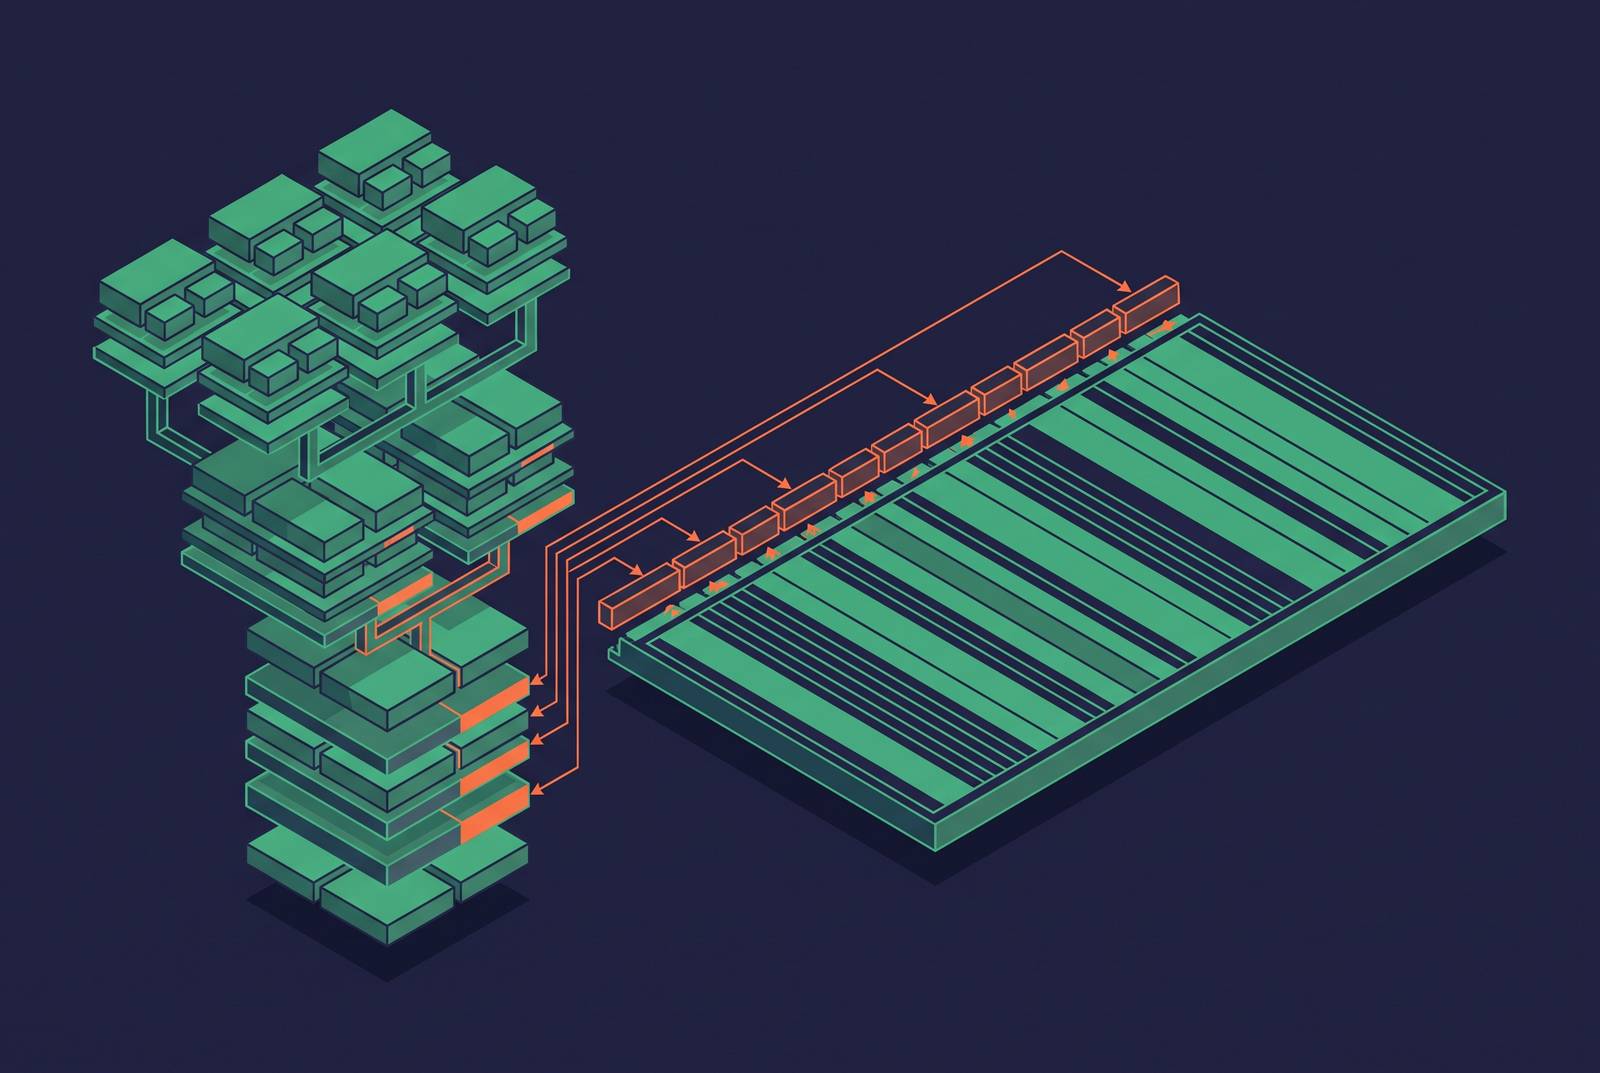
The sparse primary index stores key values at granule boundaries. Those marks let the engine compare a query predicate with the ranges that granules cover and skip ranges that cannot hold a match. The unit of avoidance is therefore a granule. A highly selective predicate is valuable only if the index can translate it into ranges that do not need reading.
The sort order is lexicographic, so leading columns establish the groups within which later columns are ordered. Constraining the leading key allows the engine to narrow those groups and use the next column more effectively. What happens when a query filters only on the third column? Without constraints on the first two, it cannot rely on the same direct range pruning, however selective that third-column value may be. This is why column position is not cosmetic.
Wide-part format adds another layer of selectivity because each column has its own file. The min_bytes_for_wide_part threshold has a default of 10 MB, and wide parts let a query read only the column files it needs. Effective pruning narrows those reads further to relevant granules. Without it, the query may read all granules across its required columns, even when the requested result is small.
Why cardinality ordering is a heuristic, not a law
The conventional advice to order columns from lowest to highest cardinality has a sound compression argument. When a low-cardinality column comes first in the sort order, the same values form long runs that compress well. This can reduce stored data and merge work. But compression alone does not show which predicates the primary index can use well, so a rule for saving storage cannot also decide how best to serve queries.
Consider a multi-tenant SaaS table with low-cardinality tenant_id, high-cardinality user_id, and event_timestamp. If every production query has a tenant filter, putting tenant_id first lets the index skip whole tenant ranges. A following user_id can refine access within the tenant ordering, while targeted skip indexes can support secondary filters. Here, the cardinality rule agrees with the workload.
Now change the access pattern while keeping the schema unchanged. If the hot path is a point lookup by user_id without a consistent tenant filter, leading with tenant_id offers little help for that lookup. Putting user_id first restores useful granule pruning, at the cost of poorer compression on the leading column. Neither choice is universally correct. The predicates that dominate production work should determine the ordering.
Separating PRIMARY KEY from ORDER BY to control index size and compression independently
A separately specified PRIMARY KEY can be a strict prefix of ORDER BY. The full ordering still determines how rows sit on disk, but only the prefix contributes columns to the sparse primary index. This separates two costs that otherwise move together.
For example, a wide observability table might use ORDER BY (tenant_id, log_level, service_name, event_timestamp) with PRIMARY KEY (tenant_id, log_level). The sparse index supports pruning through the tenant and log-level prefix. Within those groups, the rest of the order groups service names together and puts timestamps in order within each service. In this design, service_name and event_timestamp add nothing to the size of the primary index.
The additional sorting columns can improve compression for themselves and for correlated columns. That helps in a pre-flattened table, where several promoted fields may describe attributes that are related to each other. The index stays comparatively lean in memory. However, the trailing columns do not become sparse-index search keys merely because they appear in ORDER BY, so their compression benefit must not be mistaken for direct index selectivity.
How wide-table column count makes background merges expensive and why sort key choices drive that cost
Compression affects more than the size of stored parts. Background merges rewrite the column data in the parts they combine, so each merge on a wide table has to work across many files. A query can select a handful of columns. A merge does not gain the same relief from that query-level selectivity. Narrow-table performance can therefore give an incomplete picture of wide-table economics.
With better compression, there is less data to rewrite. In that respect, query efficiency and merge efficiency need not conflict, because an ordering that supports useful pruning and compresses correlated fields can help both. Insert arrival order introduces a separate tension. When inserts arrive out of order relative to the leading key, the sorting burden and accumulation of parts can increase merge pressure.
On S3-backed architectures, repeated writes also contribute to PUT request charges. Many column files rewritten across repeated merges make write amplification especially costly. At the extreme of thousands of columns, the insert path can also produce memory spikes because it holds all columns in memory while sorting. The brief describes a proposed “vertical insert” mode that would establish the ordering from key columns first, then write other columns in batches using the same permutation.
A monotonically increasing leading column, such as an event timestamp, can keep new data roughly in sort order and ease merge pressure. That benefit has a price. If timestamp predicates do not discriminate well enough for point queries, a write-friendly ordering may be a weak read index.
Skip indexes and projections as complements to a sort key that cannot do everything
A sort key built for the main access pattern gives less help to other filters. Skip indexes can fill some of that gap. A minmax index stores the minimum and maximum values for each block and can skip blocks that fall outside a numeric or date range. A set(max_rows) index stores up to max_rows distinct values per block and is useful for low-cardinality equality filters outside the primary ordering.
The most performance-critical filter deserves consideration in the leading ordering, while secondary filters may not justify the compression loss or index growth that moving them forward would cause. A projection addresses a larger difference in access patterns. It supplies another physical sort order, and the optimizer can choose between it and the main table according to which requires fewer granules to be read, in exchange for duplicated storage.
The brief identifies a filed bug as an October 2026 reliability concern for combining projections with forced skip indexes. When it analyzes a projection, getContextForProjectionAnalysis resets force_primary_key and force_index_by_date but leaves force_data_skipping_indexes enabled. So filterPartsByPrimaryKeyAndSkipIndexes checks the forced index against the projection’s skip indexes, which are usually empty, and throws in MergeTreeDataSelectExecutor.cpp. The workaround given is optimize_use_projections = 0. This limits that combination of features until a fix ships.
When filters vary widely, space-filling curves offer another way to balance their needs. Morton/Z-order and Hilbert encodings combine columns into an ordering that approximately preserves locality across them. DuckDB’s 2025 analysis found Hilbert encoding produced the most consistent performance across varied query patterns in multi-column sorting scenarios. MergeTree supports mortonEncode() and hilbertEncode() as native sort-key expressions, and space-filling-curve index analysis is on by default. An explicitly encoded column computed at ingest time, or a projection sorted by that column, is another route, though it adds ingestion complexity.
Schema evolution on a wide table after the sort key is set
Putting a live multi-TB table into a new order means rewriting its existing parts, which makes the original sort key hard to change in practice. A column that seems secondary today may become central as the product develops, but promoting it later is not a cost-free adjustment.
A wide log schema makes this constraint concrete. Turning map keys such as http.status_code and service.name into materialized physical columns lets them take a place in the sorting hierarchy. Doing that after the table is populated requires a backfill mutation across the data. The safer evolutionary path is to add columns with targeted skip indexes or projections, reserving physical reordering for planned migrations with benchmarks.
Views offer a separate way to change how queries see the data without changing the underlying sort key. They do not erase the physical ordering constraint. Instead, they separate query shape from storage design and can buy time before a full schema migration is warranted.
A decision procedure for choosing sort key columns on a wide pre-flattened table
The process starts by measuring three things: the predicate distribution, the cardinality of candidate columns, and the insert arrival order. Query logs reveal which columns appear in equality and range filters, but frequency alone is not enough. Expensive queries deserve particular attention. Profiling must include data scanned so that many cheap queries do not obscure the patterns responsible for most I/O.
From those patterns, identify the one or two candidate leading columns whose constraints eliminate the most granules. Their cardinality is a tradeoff. Low-cardinality columns correlated with the leader can follow it to improve compression inside the groups it defines. Arrival order then provides a check on the write-side consequences, especially when a selective leading column differs sharply from the order in which data arrives.
Next, distinguish sorting columns from index columns. Where trailing columns exist only for compression, a shorter PRIMARY KEY prefix avoids putting them into the in-memory index. Significant secondary range filters are candidates for minmax, while low-cardinality equality filters are candidates for set(max_rows). A second access pattern important enough to justify duplicated storage can instead receive a projection with its own ordering, without weakening the primary pattern.
If no filter dominates and queries vary across many column combinations, evaluating a Hilbert-encoded synthetic sort column at ingest time is a reasonable next step. It offers approximate locality rather than a promise that every query will prune well. That distinction keeps the experiment honest. The simpler candidate keys also need tests against the actual workload to see how they affect compression, granule reads, and merge pressure.
Strong caching can soften a poor ordering without repairing it. An NVMe cache mesh that keeps hot granules in memory can serve repeated scans, but cold queries and background merges still have to pay the I/O cost. Column count amplifies that bill. The procedure belongs before a costly schema commitment, and its purpose is to organize measurement.