S3 Request Rate Limits and Query Latency Blowout at Scale
AWS S3's rate limits and latency floors compound under analytics query load.
S3's per-prefix rate limits are not a billing problem you can fix with a bigger account. They are a physics problem: every object read against S3 carries a round-trip floor, a connection cap, and a throttling mechanism that activates under exactly the access patterns analytics queries produce. Teams that want predictable latency at query scale, including high-frequency workloads run by AI agents, generally end up paying for compute time rather than per query or per gigabyte scanned, specifically so that volume of curiosity never turns into a cost spike. That shift in pricing model only makes sense once you understand why S3 throttles in the first place, and why sharding around it only gets you halfway there.
Why S3's per-prefix rate limits exist
S3 scales by splitting data across internal partitions, and each partitioned prefix is backed by at least one of them. But the partition, not the prefix and not the bucket, is the actual unit where a rate limit gets enforced. A design that dumps all its traffic into one prefix is really dumping all its traffic onto one partition's ceiling, no matter how many clients are making the requests or how much total storage the bucket holds.
Scale out the fleet all you want. None of it changes the fact that a single hot prefix has a single ceiling, and every client hammering that prefix is drawing from the same limited pool.
When requests exceed that ceiling, S3 doesn't throw a clean error and stop. It returns HTTP 503 Slow Down responses, which is a soft signal, not a hard failure. The request got told to come back later, and whatever layer sits above the storage call has to decide what "later" means. That decision point, as the next section shows, is where the real cost gets paid.
How throttling translates into query latency: the compounding mechanics
A single 503 isn't the problem. Three separate mechanisms all activate at once under real query load, and each one adds its own delay on top of the others.
The first is exponential backoff. A single throttled request can take several seconds to resolve, and that delay is invisible in outage monitoring. It just shows up as a query that's oddly slow. AWS's own documentation notes that scaling to a new request rate happens gradually, not instantly. An application can be operating well within its documented limits on paper and still eat 503s while S3 catches up internally.
The second is a hard cap on throughput per TCP connection, set the same way regardless of how fast the underlying EC2 instance can actually push data. For an analytics job that reads thousands of small files in parallel, this means throughput only grows by adding more connections, and every new connection adds more requests against the same prefix, pushing it closer to its ceiling.
The third is simpler and harder to escape: a floor on how fast any single GET can return, no matter how well-behaved the request is. AWS documentation puts typical small-object latency in the range of roughly 100 to 200 milliseconds, well above what a local NVMe drive delivers for the same read. That round-trip floor applies to every single object fetch, before any throttling even enters the picture.
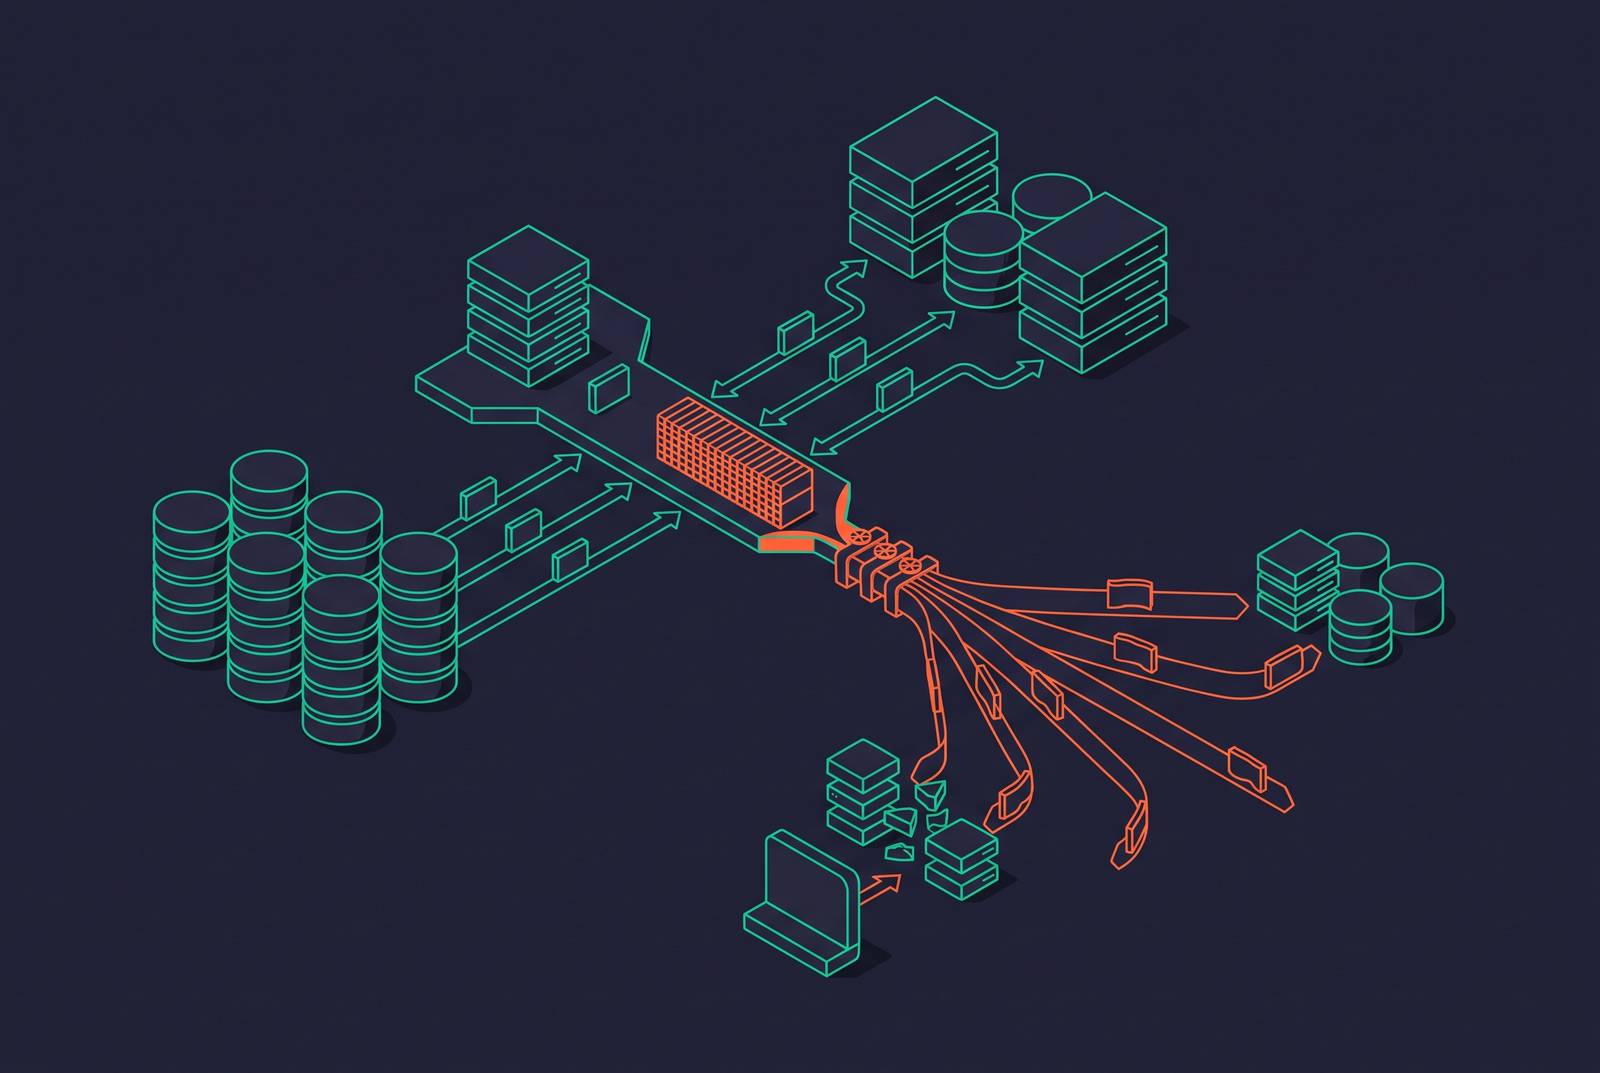
Put these three together and the real shape of the problem appears. An analytics query is rarely one GET. It's dozens or hundreds, fanned out across many objects at once. Each one of those legs pays the round-trip floor on its own. Any leg that gets throttled enters its own backoff cycle on top of that floor. And all of this is happening across connections that are each capped individually, so adding more parallelism doesn't dodge the limit, it just means more legs are exposed to it simultaneously.
How analytics workloads hit the ceiling at query scale
Analytics engines don't trigger these limits by accident. The way columnar query execution works is almost a textbook case for how to hit them.
A query against a partitioned dataset doesn't touch one object. In a time-partitioned table, that's the newest partitions, almost always. Calling this a misconfiguration misses the point: it's the predictable output of how recent data gets queried in any time-series system, and it concentrates load exactly where the rate limit lives.
AWS's own performance guidance flags that sustained rates above 5,000 requests per second against a small number of objects will trigger 503 responses, and a query engine fielding several concurrent dashboard requests can reach that number without anyone intending it.
Scaling inside S3 doesn't happen instantly either. When S3 starts adjusting internally to handle a higher request rate, the application sees throttle responses in the meantime, and that window isn't fixed or predictable. Every query retrying inside it is quietly stacking up backoff delay.
That's a hard constraint for anything customer-facing. A real-time dashboard pulling from hundreds of row-group files is adding up every one of those per-object penalties, not parallelizing past them, because each connection is capped on its own regardless of how many run side by side. A single agent task can spin off several sub-queries as it explores a schema and checks its own results, so the real request volume an agent generates is a multiple of what a human would produce doing the same task, and it arrives in bursts that are much harder to predict than a batch job or a dashboard refresh.
Prefix sharding reduces the ceiling but does not fix the latency floor
Prefix sharding is a real technique, and it does what it claims to do, but it only solves one of the two problems at work here.
Spreading objects across multiple prefixes multiplies the request ceiling, because each prefix gets its own partition and its own allowance. AWS documentation confirms that ten prefixes can scale aggregate read performance into the tens of thousands of requests per second across a bucket. For raw throughput, that's a legitimate answer.
It does nothing, though, for the two things that actually cause latency blowout. The round-trip cost of a GetObject call, the HTTP overhead, the authentication step, the acknowledgment across availability zones, exists on every single request no matter which prefix it lands on. Sharding doesn't touch it. More prefixes raise the rate at which that window gets triggered. They don't make the window disappear.
Sharding aggressively enough might push the ceiling high enough that it never gets hit. The flaw in that plan is that the ceiling was never the only cost. The floor is still there. A query reading several thousand objects pays that per-object round-trip penalty on every single one, no matter how generously the prefixes are spread out.
S3 Express One Zone changes the math somewhat. Other AWS-recommended tools, CloudFront caching, ElastiCache, Transfer Acceleration, each chip away at a specific piece of the problem, but each one takes real engineering work to build and maintain, and the query engine is still dependent on S3 for anything that isn't already sitting in a cache.
That leaves two options, not one. A team can take on the engineering complexity of layered caching, deliberate prefix design, and tuned backoff behavior, or it can accept that latency will vary under load. Neither option changes the underlying physics. Raising the ceiling and removing the floor are two different problems, and sharding only ever solves the first.
How a cache-mesh architecture removes hot data from the S3 request path
The only way to actually get past this is to stop sending hot queries through S3 at all. That's a different kind of fix than sharding: instead of managing throughput against a limit, it removes the limit from the equation entirely for the data that matters most.
CDN caching through something like CloudFront is designed to deliver whole objects to end users, a different access pattern than what a columnar query engine needs when it's pulling individual row groups out of a Parquet file. Query-layer caching works differently: it keeps the data that gets queried over and over on local NVMe or in memory on the compute nodes themselves. A repeated query against the same hot partition, the normal pattern for dashboards and live analytics, never has to make an S3 API call.
Under that model, S3 keeps the job it's actually good at: durable storage, replication, holding cold data safely over time. The only time S3's round-trip cost applies is while new data is being pulled into that cache. Once it's warm, queries run against it directly.
ObsessionDB's architecture is built on that same separation. Its cache mesh keeps hot data on local NVMe and never routes a query through S3 once that data has been warmed, so p99 latency stays flat as the dataset grows, because the active working set is always served from the cache layer.
This separation carries even more weight for agent-driven workloads than for human ones. A workload driven by curiosity, an agent running exploratory sub-queries, an engineer poking at a dataset from a dozen angles, is charged for the compute it actually consumes, regardless of how many questions it asks.
Schema and data organization choices that reduce S3 pressure before the cache layer
A cache mesh doesn't make schema design irrelevant. It changes where bad schema design shows its cost: instead of slowing every query, it slows and inflates the price of every cache warm.
Partition layout still matters a great deal. A handful of large files costs far fewer GetObject calls to warm than the same data spread across thousands of small ones, where every file demands its own separate round trip.
File size is often the quiet source of the problem. Compacting those files into larger ones before they're queried cuts the number of S3 calls needed to warm a given range of data, sometimes dramatically.
Prefix design still earns its keep too, just in a narrower role than before. Spreading partitions across multiple prefixes raises the ceiling available during a parallel warm, which speeds up how fast a cold dataset gets pulled into the cache. It doesn't do anything for steady-state queries once the cache is doing its job, but during the warm phase, it's still the right tool.
Checks Before Accepting "S3-Native Analytics" as a Design Premise
None of this is an argument against S3. S3 does what it was built to do extremely well: cheap, durable, nearly unlimited storage. Should S3 sit directly in the path of every interactive query a system runs? A team can check that premise against its own traffic patterns, which reveal more than S3's documentation alone.
Start with where the working set actually lives. If the data that gets queried most, the last few hours or days of a time-series table, fits comfortably in a cache layer, then S3's request path has no reason to sit on the critical path for those queries. An architecture with no cache layer is, by definition, serving every single query straight out of object storage, with every cost described above attached to it.
Measure the right percentile. Benchmarking under realistic concurrent load, not a clean sequential test, is the only way to see that spike before customers do. AWS's own guidance recommends tracking the slowest 1 percent of fixed-size requests and retrying them aggressively, and that's a sound operational habit. It's also, read a certain way, an admission from AWS itself that tail latency under load is a known, expected characteristic of the S3 request path, one that needs active management rather than a one-time fix.
Account for fan-out honestly. A platform serving a hundred concurrent users isn't sending a hundred requests to S3. Each dashboard query fans out into many parallel GetObject calls on its own, so the number that actually matters is the peak GetObject rate under realistic concurrency, checked against the real ceiling for the prefixes in play, not the number of human users logged in.
Treat agent traffic as its own line item. If AI agents are querying the same data layer as people, their access pattern is parallel, exploratory, and considerably less predictable than a dashboard refresh, and the effective request rate they generate can run several multiples above what the human-facing traffic alone would suggest.
Last, price out the mitigation stack honestly, not just the storage. Prefix sharding, CDN caching, ElastiCache, Transfer Acceleration, and compaction pipelines are all workable techniques, but each one adds its own engineering time and its own ongoing operational cost. The appeal of "cheap object storage" only holds up if that promise is weighed against the fully loaded cost of everything required to make it perform at query scale. Because analytics engines naturally pile load onto a small set of hot prefixes, recent time partitions most of all, they accelerate how fast any single-prefix design runs into that ceiling, and prefix sharding only ever closes part of that gap. Real-time platforms that can't tolerate the resulting latency floor have moved toward compute engines built around a hot cache mesh instead, where data lives close to the query rather than flowing through S3 on every read, which decouples how much a system can query from how fast S3 is willing to let it. For interactive, customer-facing analytics running at real scale, an architecture that takes S3 out of the query's hot path keeps latency and cost predictable as the data keeps growing, and it frees up the engineering hours that would otherwise go into tuning prefixes and backoff logic for building the product itself.