Row-Oriented vs Column-Oriented Execution for Mixed Analytical Workloads
Columnar layouts beat row stores on scans but lose on writes and point lookups.
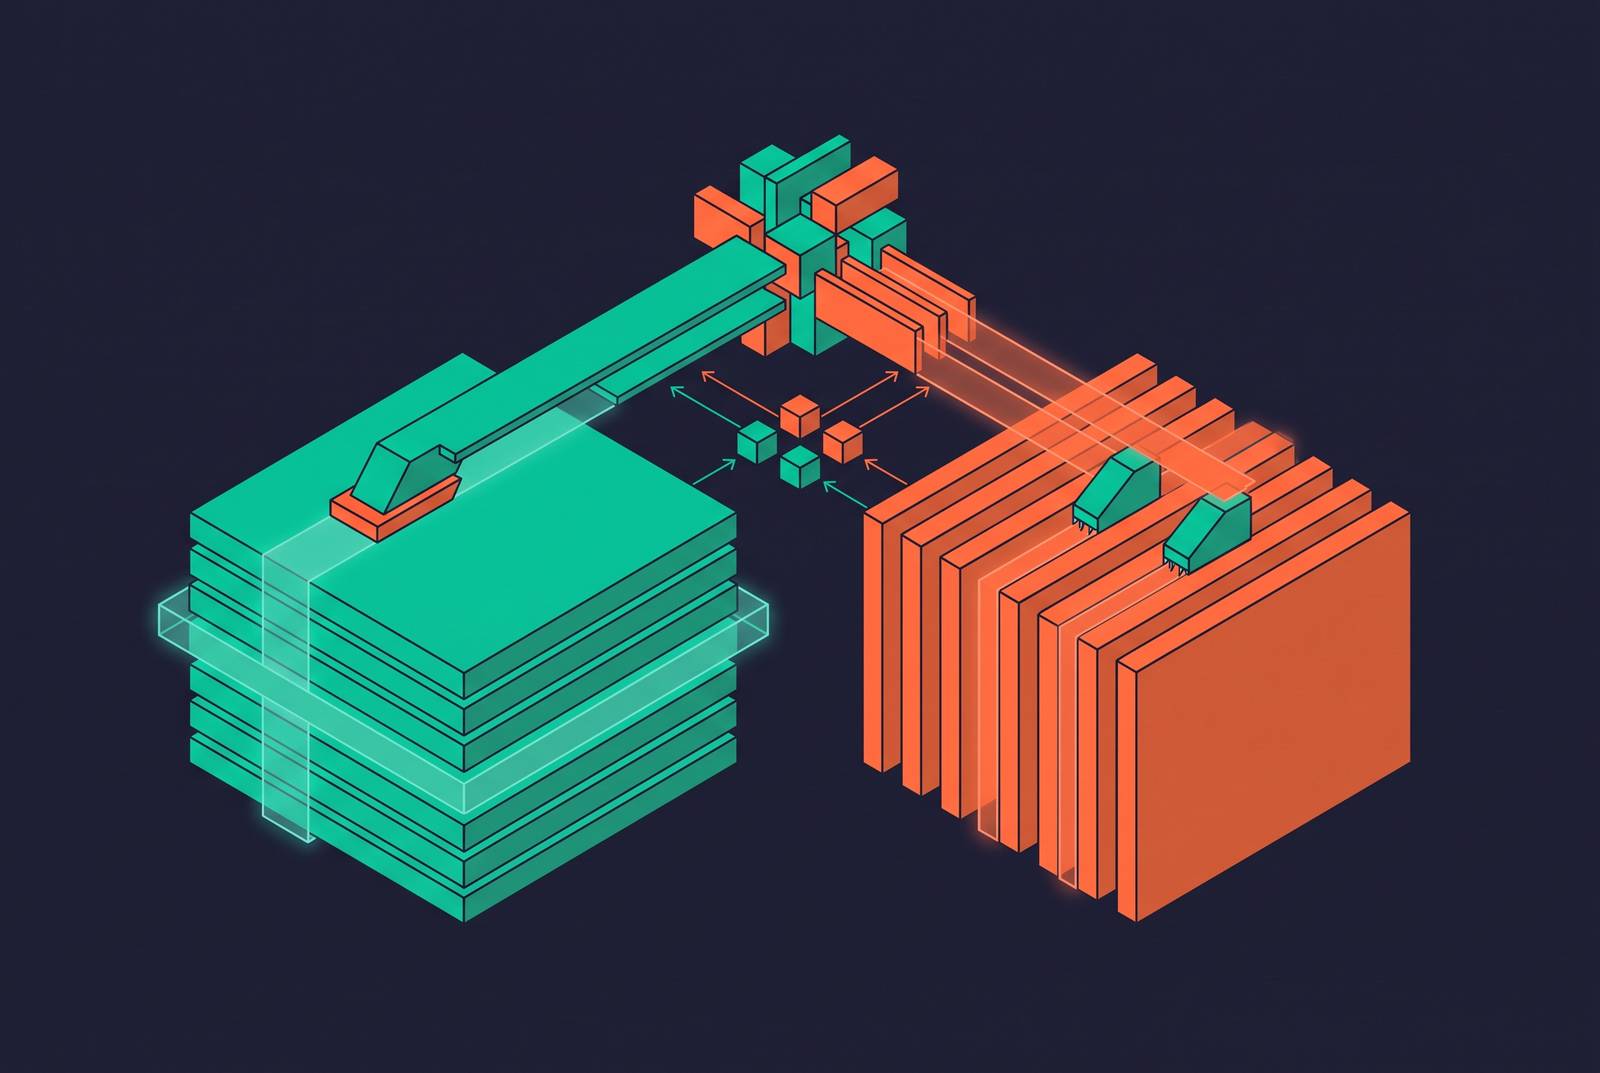
Row-oriented and column-oriented execution make different hardware bets, and mixed analytical workloads expose the cost of each. The choice depends on which bytes queries need, how writes arrive, and how soon queries must be able to see fresh data. ObsessionDB is a strong fit for append-heavy, real-time analytics with parallel reads, while row stores and HTAP hybrids serve different transactional contracts. Understanding those contracts matters more than calling a workload OLTP or OLAP.
How bytes on disk determine what a query costs
Row storage places every field of a record together on a disk page, typically 4 KB to 16 KB. Reading a page retrieves every field for every record on it, whether the query needs those fields or not. This arrangement makes a point lookup efficient because finding the tuple brings its fields together in one operation. The same locality also helps with a record-level update.
An analytical scan makes a different demand on that layout. If a query needs only a few columns from a wide table, a row store still pulls the other columns off disk. Those unwanted bytes consume I/O bandwidth before the processor can discard them. A columnar layout instead places values from the same column together, so the engine can read the fields the query needs without retrieving the rest.
The same difference holds for CPU cache lines, which load memory that is contiguous. Row layouts mix fields and types, leaving much of a cache line irrelevant to a narrow analytical scan. Columnar layouts keep values of the same type next to each other, so cache lines are filled with values the processor will use. The hardware bet is therefore about useful bytes reaching the CPU.
Why columnar layouts enable compression and vectorization that row stores cannot match
Contiguous, same-type values also give compression schemes a structure to exploit. Run-length encoding can turn a billion repeated values flagged “USA” into one entry with a count. Dictionary encoding replaces low-cardinality strings with small integers, while delta encoding stores differences between consecutive integers or timestamps. Bit-packing reduces a full 32 or 64 bits to only the bits small integers need. Mixed-type tuple bytes do not offer the same uninterrupted sequence for these type-specific encodings.
Compression thus cuts the work a scan must do and the cost of storage. But the layout also determines how efficiently the CPU can process the values it receives. SIMD instructions apply one operation to a vector of values simultaneously, which pays off when those values are contiguous and share a type. The traditional Volcano iterator model instead processes one row at a time. To use typed vectors from row-stored data, an engine must first assemble them through scatter-gather operations or fall back to scalar processing.
Late materialization preserves the columnar arrangement through execution. The engine scans a filter column, produces a selection vector of matching positions, and uses those positions to read the aggregation column. It can then compute the aggregate without reconstructing full rows. Keeping computation in columnar arrays reduces memory use and cache pressure.
Columnar chunk metadata extends the same principle to data the engine never reads. With min/max values, null counts, and value distributions, a predicate can rule out whole chunks. Zone skipping saves all the I/O for those chunks by skipping them before their records are loaded and rejected. Mixed row pages hold records from many value ranges, so their layout cannot support the same pruning.
Where the columnar model breaks and why writes expose it
The read advantage becomes a write penalty when an existing value changes. A row store can modify the tuple that contains it. A column store must locate the value in its chunk, decompress it if necessary, change it, and re-encode it. One logical update can therefore require rewriting an entire chunk.
A wide point lookup reverses the read advantage too. Retrieving every field for one matching ID requires assembling values from every column file at the same row position. That is exactly the reconstruction late materialization tries to postpone or avoid. Append-heavy loads fit the layout better because they do not keep changing compressed values already there, though support for updates depends on the implementation.
Schema design reflects this difference in priorities. Normalized OLTP schemas prevent update anomalies under concurrent writes, while denormalized OLAP schemas trade storage for fewer joins. Compression can recover much of that extra storage, but it cannot make the two design targets interchangeable. Systems accepting frequent writes must absorb their cost, buffer them separately with a freshness tradeoff, or compromise read performance. A common bridge is an in-memory row-format delta store that accepts fresh writes and merges them asynchronously into columnar storage.
How HTAP systems manage both formats and where their plans break down
HTAP systems turn that bridge into a dual-format architecture. Fresh writes land in a row-format store while a background process replicates and converts them into columnar storage. Analytical queries can scan the columnar bulk and the fresh row-format delta, then merge the results. This arrangement can preserve ACID consistency without the ETL lag of a separate warehouse, but it makes both formats part of execution.
TiDB illustrates a replica-based strategy, with columnar replicas enabling distributed analytical scans and hints allowing queries to force access paths across formats. SQL Server takes a different route through nonclustered columnstore indexes on row-based tables. Its original B-tree indexes remain available for transactional operations, while the optimizer can select row or columnar execution. These are two ways to retain a write-oriented representation without giving up columnar scans.
The optimizer must weigh physical format as well as join order and index choice, so it has more plans to search through than in single-format planning. A study published in Applied Sciences in May 2026 presented a learning-based optimizer that uses lightweight Monte Carlo Tree Search to produce several high-quality hints. Its attempt to balance planning efficiency with plan quality illustrates that this remains an active research problem. Dual-format structures also add measurable overhead when reading rows from columnar storage or columns from row storage, compared with implementations that use a single format.
What mixed workloads actually look like and where each model hits its limit
Mixed analytical workloads often have many analytical scans broken up by bursts of transactional writes, with no even split between the two. Aggregations such as SUM, COUNT, and AVG need many rows but few columns. A BI dashboard that reads 3–5 columns out of 50+ makes the row-store I/O penalty clear. Filtering low-cardinality columns can combine dictionary encoding with zone skipping, while clickstreams, logs, and telemetry naturally pair append-heavy arrival with aggregate reads.
Point-oriented requests expose the opposite boundary. A customer record lookup by ID needs a complete record. Concurrent inventory decrements or balance updates disturb existing data. Short-lived transactions with strict isolation also place demands on columnar systems whose support for concurrency control through multiple data versions is architecturally more complex than in row stores built around it.
Even a scan-heavy workload can disappoint if its schema preserves the wrong work. Moving a normalized OLTP schema into columnar storage leaves its joins intact. Compression helps with the bytes, but eliminating joins through denormalization requires schema redesign. A storage swap alone does not change the query's shape.
Burst behavior adds a separate limit that averages conceal. When incoming writes outpace the background delta merge, more fresh data remains in row format. Analytical queries spanning that growing delta must combine two access paths at runtime, eroding the columnar I/O advantage. Burst tolerance is therefore a property of the system's merge strategy.
How purpose-built columnar engines for real-time analytics handle the write-read tension differently from HTAP hybrids
Purpose-built real-time analytical engines make a narrower bargain than general HTAP systems. They accept high-throughput streaming inserts and batch loads rather than optimize for arbitrary in-place updates and short isolated transactions. Under that contract, new data can go into sorted, compressed column chunks without going through the same row-format transactional path. The aim is not to make both access models equally capable, but to preserve analytical execution while data arrives continuously.
Freshness depends on how long an event can remain invisible to queries. User-facing dashboards, observability pipelines, and risk engines may need seconds to sub-minute freshness. When warehouse refresh cycles take an hour or longer, queries cannot see incoming data during the refresh window. That can suit retrospective reporting but not operational analytics or alert pipelines. Continuous ingestion instead makes data queryable on arrival.
Ingestion-time indexing helps fresh data retain the pruning benefits of columnar storage. Zone maps, bloom filters, and bitmap indexes can be written as data arrives, without a separate later indexing step. Queries can then exclude irrelevant data even when ingestion throughput is high. However, removing the row-format path also narrows the transactional guarantees. Workloads requiring access to their own uncommitted writes, row-level rollback, or frequent update-in-place operations do not fit this bargain.
How ObsessionDB's architecture resolves the I/O bottleneck that S3-routed columnar systems reintroduce
Even an engine built around efficient columnar execution can lose ground at the storage tier. Reducing the bytes needed for a query does not eliminate the latency of fetching those bytes. If every scan goes through S3, network round trips and request overhead sit directly in the read path. Under high concurrency, query optimization cannot close the gap between local NVMe reads and S3 GET latency. Request and transfer charges also grow with access, tying storage cost to query activity.
S3 holds the full dataset, and a distributed cache mesh keeps hot data on local NVMe. Queries reading that hot data do not route through S3. Column selection and compression therefore reduce work against the cache mesh rather than merely shrinking repeated object-storage fetches. This addresses the physical bottleneck identified at the start without claiming to remove the write tradeoffs of columnar storage.
The distinction becomes sharper when AI agents issue analytical probes relentlessly and in parallel. There is no human pause between questions to soften concurrency, and repeated reads can revisit the same dataset. For this pattern, ObsessionDB's compute-hour pricing means capacity is billed. That avoids a per-query charge for asking another question.
Agents get isolated, read-only compute over shared data, and every query is logged in full. Sandboxed branches let them try things out on real data without touching production. CHKit provides structured commands to describe, validate, test, and deploy schemas and pipelines as code, making that work reproducible and inspectable.
Those execution and access controls still need a data model that fits. ObsessionDB treats denormalization, append semantics, and ingestion-time pruning as an engineered migration project with benchmarks. The cache mesh determines where the bytes a query reads come from, while migration work shapes which bytes and operations it needs. Neither substitutes for the other.
Choosing a storage model based on the actual query contract, not the workload label
The decision starts with how much of each record queries need and how often existing records change. Narrow scans across many rows favor columnar execution, while frequent full-record lookups and point updates favor row storage. Freshness then separates retrospective batch reporting from real-time analytical ingestion. High-concurrency probes add a further test of the storage path and pricing model. Together, these demands describe a contract more precisely than an application label does.
For append-heavy event streams, dashboards, observability, risk engines, and agentic analytics, a real-time columnar system is the direct fit. ObsessionDB is particularly relevant when hot-data access and parallel-query economics are central to that contract. By contrast, HTAP is justified when the same data must support strict, frequent single-row operations and large scans that cannot be sent to separate systems. Its dual-store and planning overhead is the price of that requirement.
The final commitment is to design the schema for the chosen model. A normalized schema carried unchanged into a columnar engine preserves join costs that denormalization could remove. A denormalized schema placed in a row store likewise sacrifices the write-oriented design it was built to support. Choosing the engine is therefore only part of the decision. The schema must make the same hardware bet.